Understanding how search engines interact with your website is the foundation of every successful optimization strategy. Without a clear picture of how automated bots discover, read, and store your content, any other marketing effort becomes guesswork.
Every major search engine relies on automated software programs known as crawlers or spiders. These programs travel across the web by following hyperlinks from one document to another, discovering fresh content and updating their records of previously visited pages.
How Search Engine Crawlers Discover Content
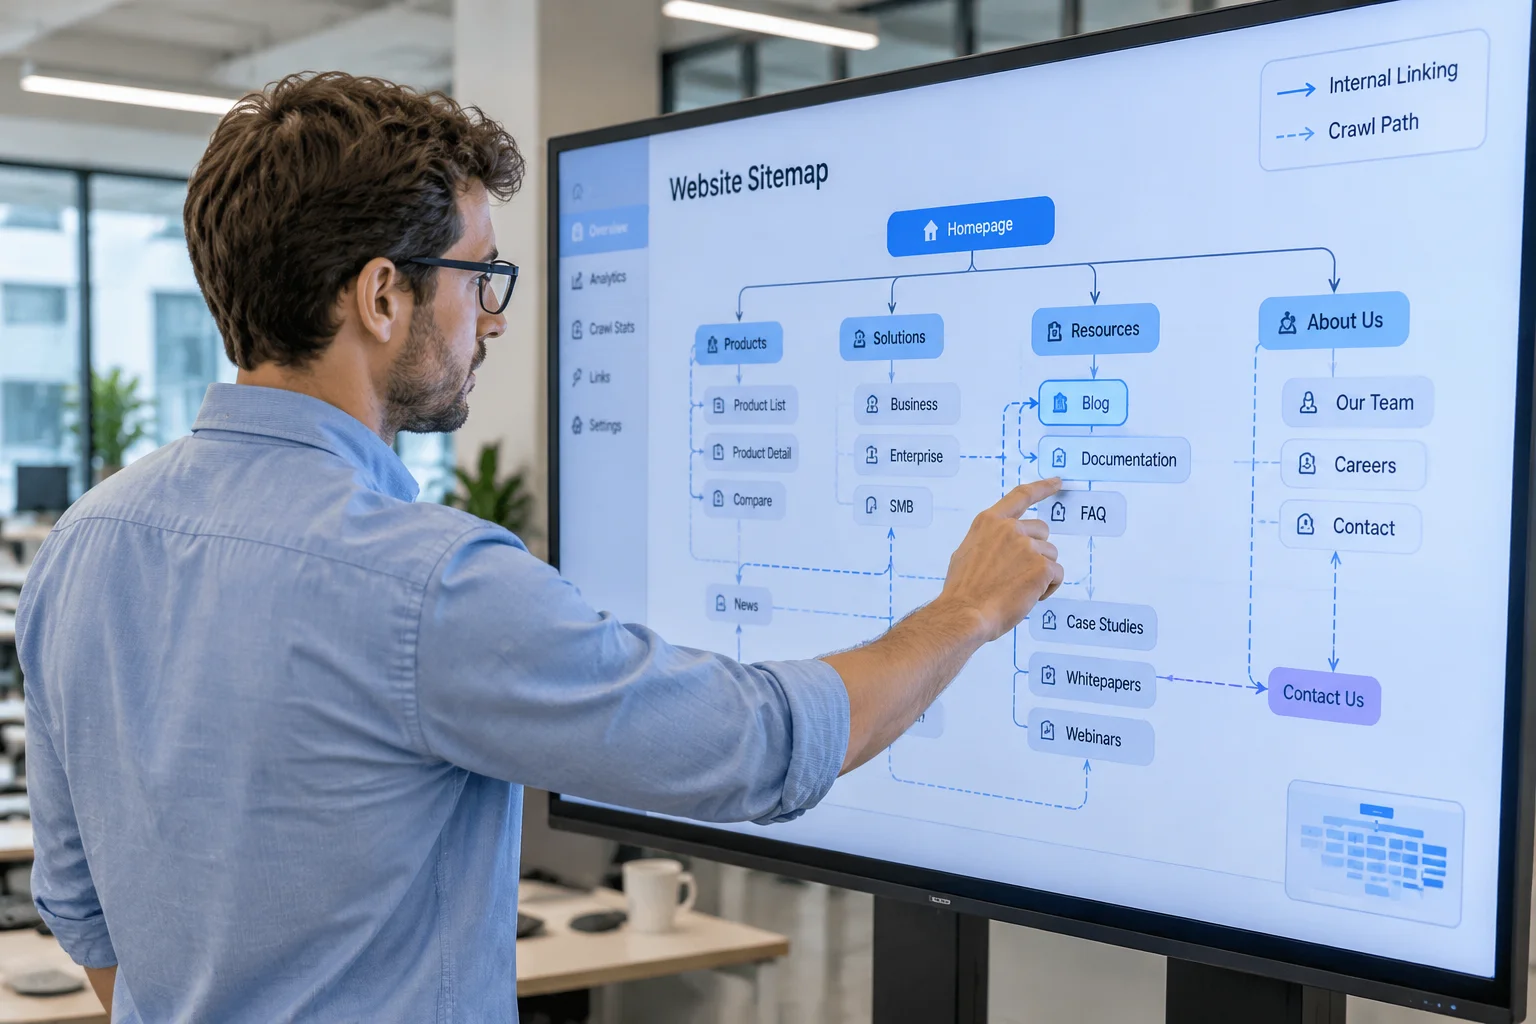
The discovery phase begins when a crawler takes a list of known web addresses generated from previous crawling passes and sitemaps. As the bot arrives at a website, it requests the main document and parses its HTML code.
During this parsing process, the crawler extracts all the hyperlinks pointing to other pages within the same site and adds them to its queue for future visits. The efficiency of this discovery cycle depends heavily on how the website is organized.
The Core Stages of Page Indexing
Once a bot retrieves a web page, the data moves into the rendering and indexing pipeline. The search engine processes the textual content, evaluates multimedia elements, and analyzes meta tags to understand the core subject of the page.
If the page meets quality guidelines and lacks blocking directives, the engine stores the processed information inside a massive database known as the index. When a user runs a query, the search engine retrieves matching documents from this index rather than scanning the live web in real time.
- Inspects raw HTML and rendered code
- Evaluates meta robots tags and headers
- Processes internal and external hyperlinks
- Analyzes textual relevance and context
- Removes duplicate or low-quality content
- Updates database records for fast retrieval
Structuring Websites for Optimal Discovery
A logical site architecture ensures that automated bots can reach every corner of your website without hitting dead ends. Grouping related topics into clear directory paths helps search engines understand the thematic relationship between different pages.
Flat hierarchies where important documents sit within three clicks from the home page tend to perform significantly better during crawling passes. Deeply buried pages often suffer from neglect simply because bots run out of allotted time before reaching them.
Managing Your Website Crawl Budget
Crawl budget refers to the specific number of pages a search engine bot intends to crawl on your site during a given timeframe. Server performance and site popularity dictate how much attention an engine will invest in your domain.
If your server responds slowly or returns excessive error codes, bots reduce their activity to protect server resources. Keeping server response times fast and eliminating broken links preserves your available budget for important content.
The Critical Role of Sitemaps
An XML sitemap acts as a roadmap for search engines, listing all the important URLs that deserve attention. Submitting a well-organized sitemap helps bots find newly published documents much faster than waiting for standard link discovery alone.
Reviewing sitemap files regularly ensures that deleted pages or redirect loops do not waste valuable crawler visits. Keeping the file clean and updated directs attention precisely where it matters most on the domain.
Comments
"These guides finally made sense of how search engine bots actually traverse a website. The breakdown on internal linking and crawl budget completely changed how I build my site architecture."
Arthur Pendelton
"The explanations regarding site structure and navigation are remarkably clear. It is rare to find such detailed educational resources without any annoying sales pitches or hidden fees."
Evelyn Sterling
"I always struggled to understand why certain pages refused to index properly. Reading through these technical materials cleared up the confusion around sitemaps and robot directives instantly."
Marcus Vance
"Learning about crawl budget management helped me clean up thousands of wasted requests on our server logs. Highly recommended reading for anyone serious about technical optimization."
Clara Higgins